the table shows the estimated number of lines of code written by computer programmers per hour when x people…
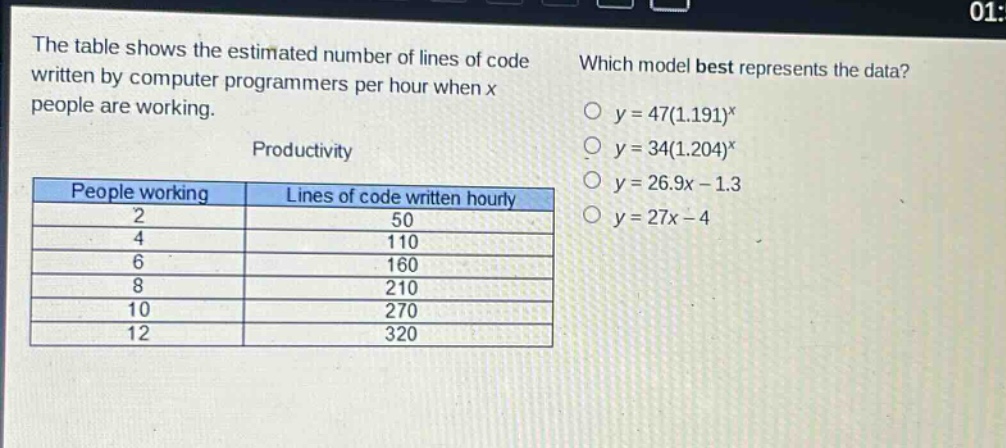
the table shows the estimated number of lines of code written by computer programmers per hour when x people are working. productivity people working lines of code written hourly 2 50 4 110 6 160 8 210 10 270 12 320 which model best represents the data? y = 47(1.191)^x y = 34(1.204)^x y = 26.9x - 1.3 y = 27x - 4
Answer
Answer:
$y = 26.9x - 1.3$
Explanation:
Step1: Check linear - exponential nature
As $x$ (people working) increases by a constant amount (2), $y$ (lines of code) increases by approximately a constant amount. So, it is likely a linear model. We can rule out the exponential models $y = 47(1.191)^x$ and $y = 34(1.204)^x$.
Step2: Test linear models
For a linear model $y=mx + b$, we can use two - point form to find the slope $m=\frac{y_2 - y_1}{x_2 - x_1}$. Let's take $(x_1,y_1)=(2,50)$ and $(x_2,y_2)=(4,110)$. Then $m=\frac{110 - 50}{4 - 2}=\frac{60}{2}=30$. For the model $y = 26.9x-1.3$, when $x = 2$, $y=26.9\times2-1.3=53.8 - 1.3 = 52.5$ (close to 50). When $x = 4$, $y=26.9\times4-1.3=107.6-1.3 = 106.3$ (close to 110). For the model $y = 27x - 4$, when $x = 2$, $y=27\times2-4=54 - 4=50$. When $x = 4$, $y=27\times4-4=108 - 4 = 104$ (less close to 110 compared to $y = 26.9x - 1.3$). So $y = 26.9x - 1.3$ best represents the data.